Available for Opportunities

Hello, I'm

Vivek Basavanth
Hanagoji

I build
Vivek Basavanth Hanagoji
Scroll
Who I Am

About Me

Vivek

Name: Vivek Basavanth Hanagoji

Role: Data Engineer 2

Company: Kraft Analytics Group (KAGR)

Location: Boston, MA

Core Skills
SQL & Data Modeling95%
Python & PySpark90%
dbt & Kimball Modeling90%
Snowflake / Redshift / BigQuery88%
Airflow & Spark85%

Data Engineer with 3+ years of experience designing distributed pipelines, cloud warehouses, and data quality frameworks across Python, SQL, Spark, Snowflake, dbt, and AWS. Currently at Kraft Analytics Group (KAGR) — building production fan engagement analytics for all NFL partner teams. Comfortable owning systems end to end, from raw ingestion through modeling to production dashboards.

  • ProfileData Engineering & Analytics
  • EducationM.S. Computer Software Engineering · Northeastern University
  • LanguagesPython, SQL, JavaScript, HTML/CSS
  • Cloud & DWAWS (S3, EC2, EMR, Glue, Athena) · Snowflake · Redshift · BigQuery · Azure Data Factory
  • Big DataApache Spark, SparkSQL, Hadoop, Hive
  • OrchestrationApache Airflow, Prefect, AWS Glue, Kubernetes, Talend, Alteryx
  • Data Modelingdbt, Kimball, SCD Type 1/2/4, ETL/ELT Design, Data Quality Testing
  • BI ToolsPower BI, Tableau, Looker Studio
  • InterestsTraveling, Travel Photography

0  +  Projects completed

Career

Work Experience

Building production-grade data systems across sports analytics, enterprise telecoms, and the cloud.

Jun 2025 — Present

Data Engineer 2 Current

Kraft Analytics Group (KAGR)  ·  Boston, MA
  • Architected multi-tenant fan engagement analytics by integrating unsubscribe activity into email export pipelines (Snowflake SQL, Python), enabling precise audience delivery across 8M+ contact records for all NFL partner teams.
  • Built a Python GraphQL ingestion layer from the Shopify API that unnested 5-level nested JSON, serialized to Parquet via PyArrow, cutting per-batch file size 77% (2.1GB → 480MB) before landing in AWS S3; eliminated 3M duplicates.
  • Engineered a 5-stage dbt lineage for an NFL client — flatten, Melissa API standardization, deduplication, and merge — version-controlled and deployed via CircleCI.
  • Authored dbt generic tests enforcing uniqueness and referential integrity, proactively catching 4 upstream schema breaks before they reached partner-facing dashboards.
  • Designed an anonymization match-pass for KAGR's multi-source identity resolution pipeline (Archtics, Shopify, Salesforce, Ticketmaster, StubHub, Lava), merging 1.5M dormant records into golden audience IDs.
Snowflake dbt Python GraphQL AWS S3 PyArrow CircleCI Shopify API Salesforce Ticketmaster
Jul 2019 — Feb 2022

Data Engineer

Vodafone Intelligent Solutions (VOIS)  ·  Pune, India
  • Designed SQL-based data models in AWS Redshift enabling OLAP cube analysis for user behavior, transaction patterns, and fraud detection, powering 3 downstream analytical workflows.
  • Orchestrated daily batch ETL pipelines with Airflow and Spark, ingesting 70M+ rows (~1TB) per day of telemetry data into Redshift.
  • Implemented SCD Type 2 & Type 4 to track historical customer attributes; built Python validation routines achieving 99% data completeness.
  • Partnered with PMs and SDEs to design a secure, product-partitioned data lake optimized for Athena and Redshift queries.
Apache Spark SparkSQL Python Airflow AWS Redshift AWS S3 SQL SCD Type 2 & 4 ETL OLAP
Academic

Education

Sep 2022 — May 2024

M.S. in Computer Software Engineering

Northeastern University, Boston, MA  ·  GPA 3.6
Northeastern University

Big Data Systems & Intelligent Analytics · Advanced Data Architecture & Business Intelligence · Data Science

Jun 2015 — Jun 2019

B.E. in Computer Engineering

Savitribai Phule Pune University, Pune, India
Savitribai Phule Pune University

Fundamentals of Programming · Machine Learning · System Programming & Operating Systems

Work

Selected Projects

Data engineering and ML projects spanning SQL, Python, Power BI & deep learning.

End-to-End Reddit Data Pipeline on AWS

Production-style ETL pulling Reddit data through Airflow & Celery into S3, transformed with AWS Glue, queried via Athena, and loaded into Redshift for analytics.

View on GitHub

Real-Time Streaming Pipeline (Kafka + Spark)

Event-driven streaming architecture with Apache Kafka and Spark feeding Amazon Redshift, with infrastructure provisioned via Terraform and containerized with Docker.

View on GitHub

Snowpark Python Data Pipeline

Incremental data pipeline built on Snowpark Python stored procedures, orchestrated with Snowflake Tasks and deployed through an automated CI/CD workflow.

View on GitHub

NYC Motor Collision Analysis

Migrated 10M+ records from BigQuery to MySQL via Talend ETL. Power BI & Tableau dashboards surfacing YoY KPIs and collision trend analysis.

View on GitHub

GenAI Chatbot for SEC Documents

OpenAI-driven chatbot for 75+ SEC forms with 95% similarity search accuracy. 2 Airflow ETL pipelines, Dockerized deployment on GCP with AWS Postgres backend.

View on GitHub
Content Creator

Data with Vicky

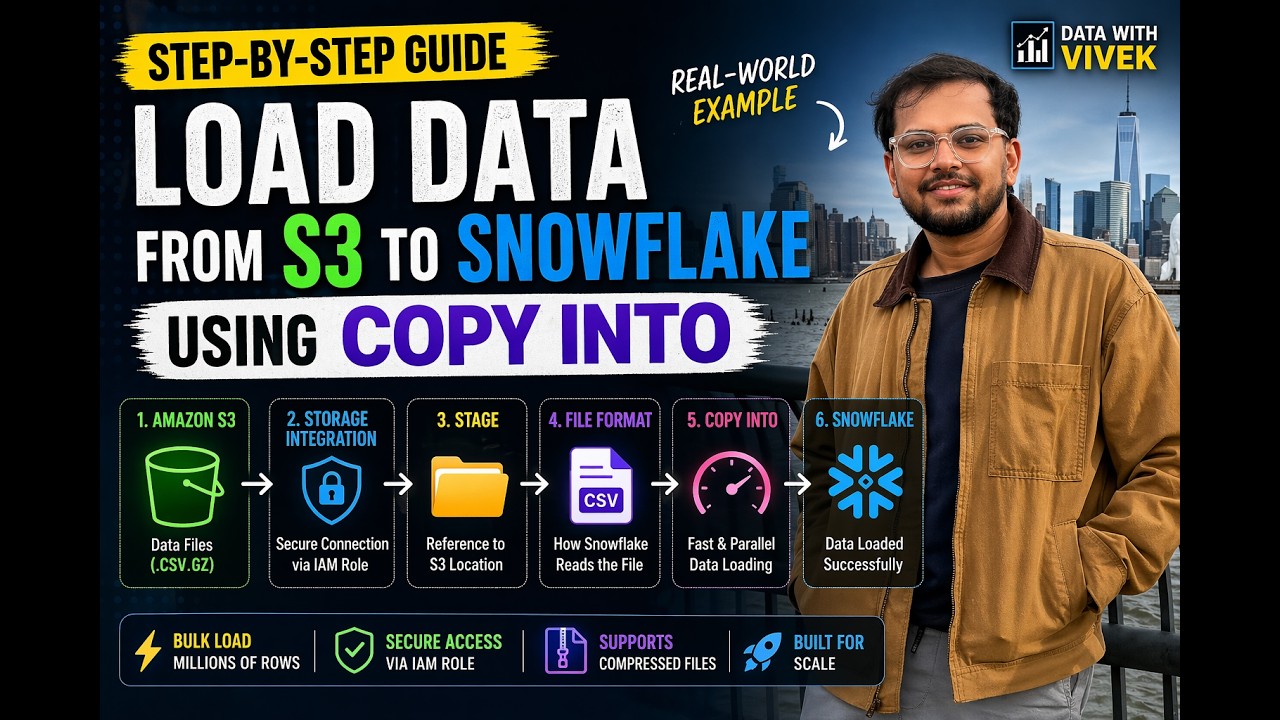
Breaking down complex data engineering concepts into simple, actionable ideas — for everyone from beginners to practitioners.

Data with Vicky

Data with Vicky

@DatawithVicky

Simplifying Data Engineering — pipelines, cloud platforms, SQL, dbt, Snowflake and more. Real concepts from real production experience.
Data Engineering Snowflake dbt Python Cloud Pipelines
Life Beyond Data

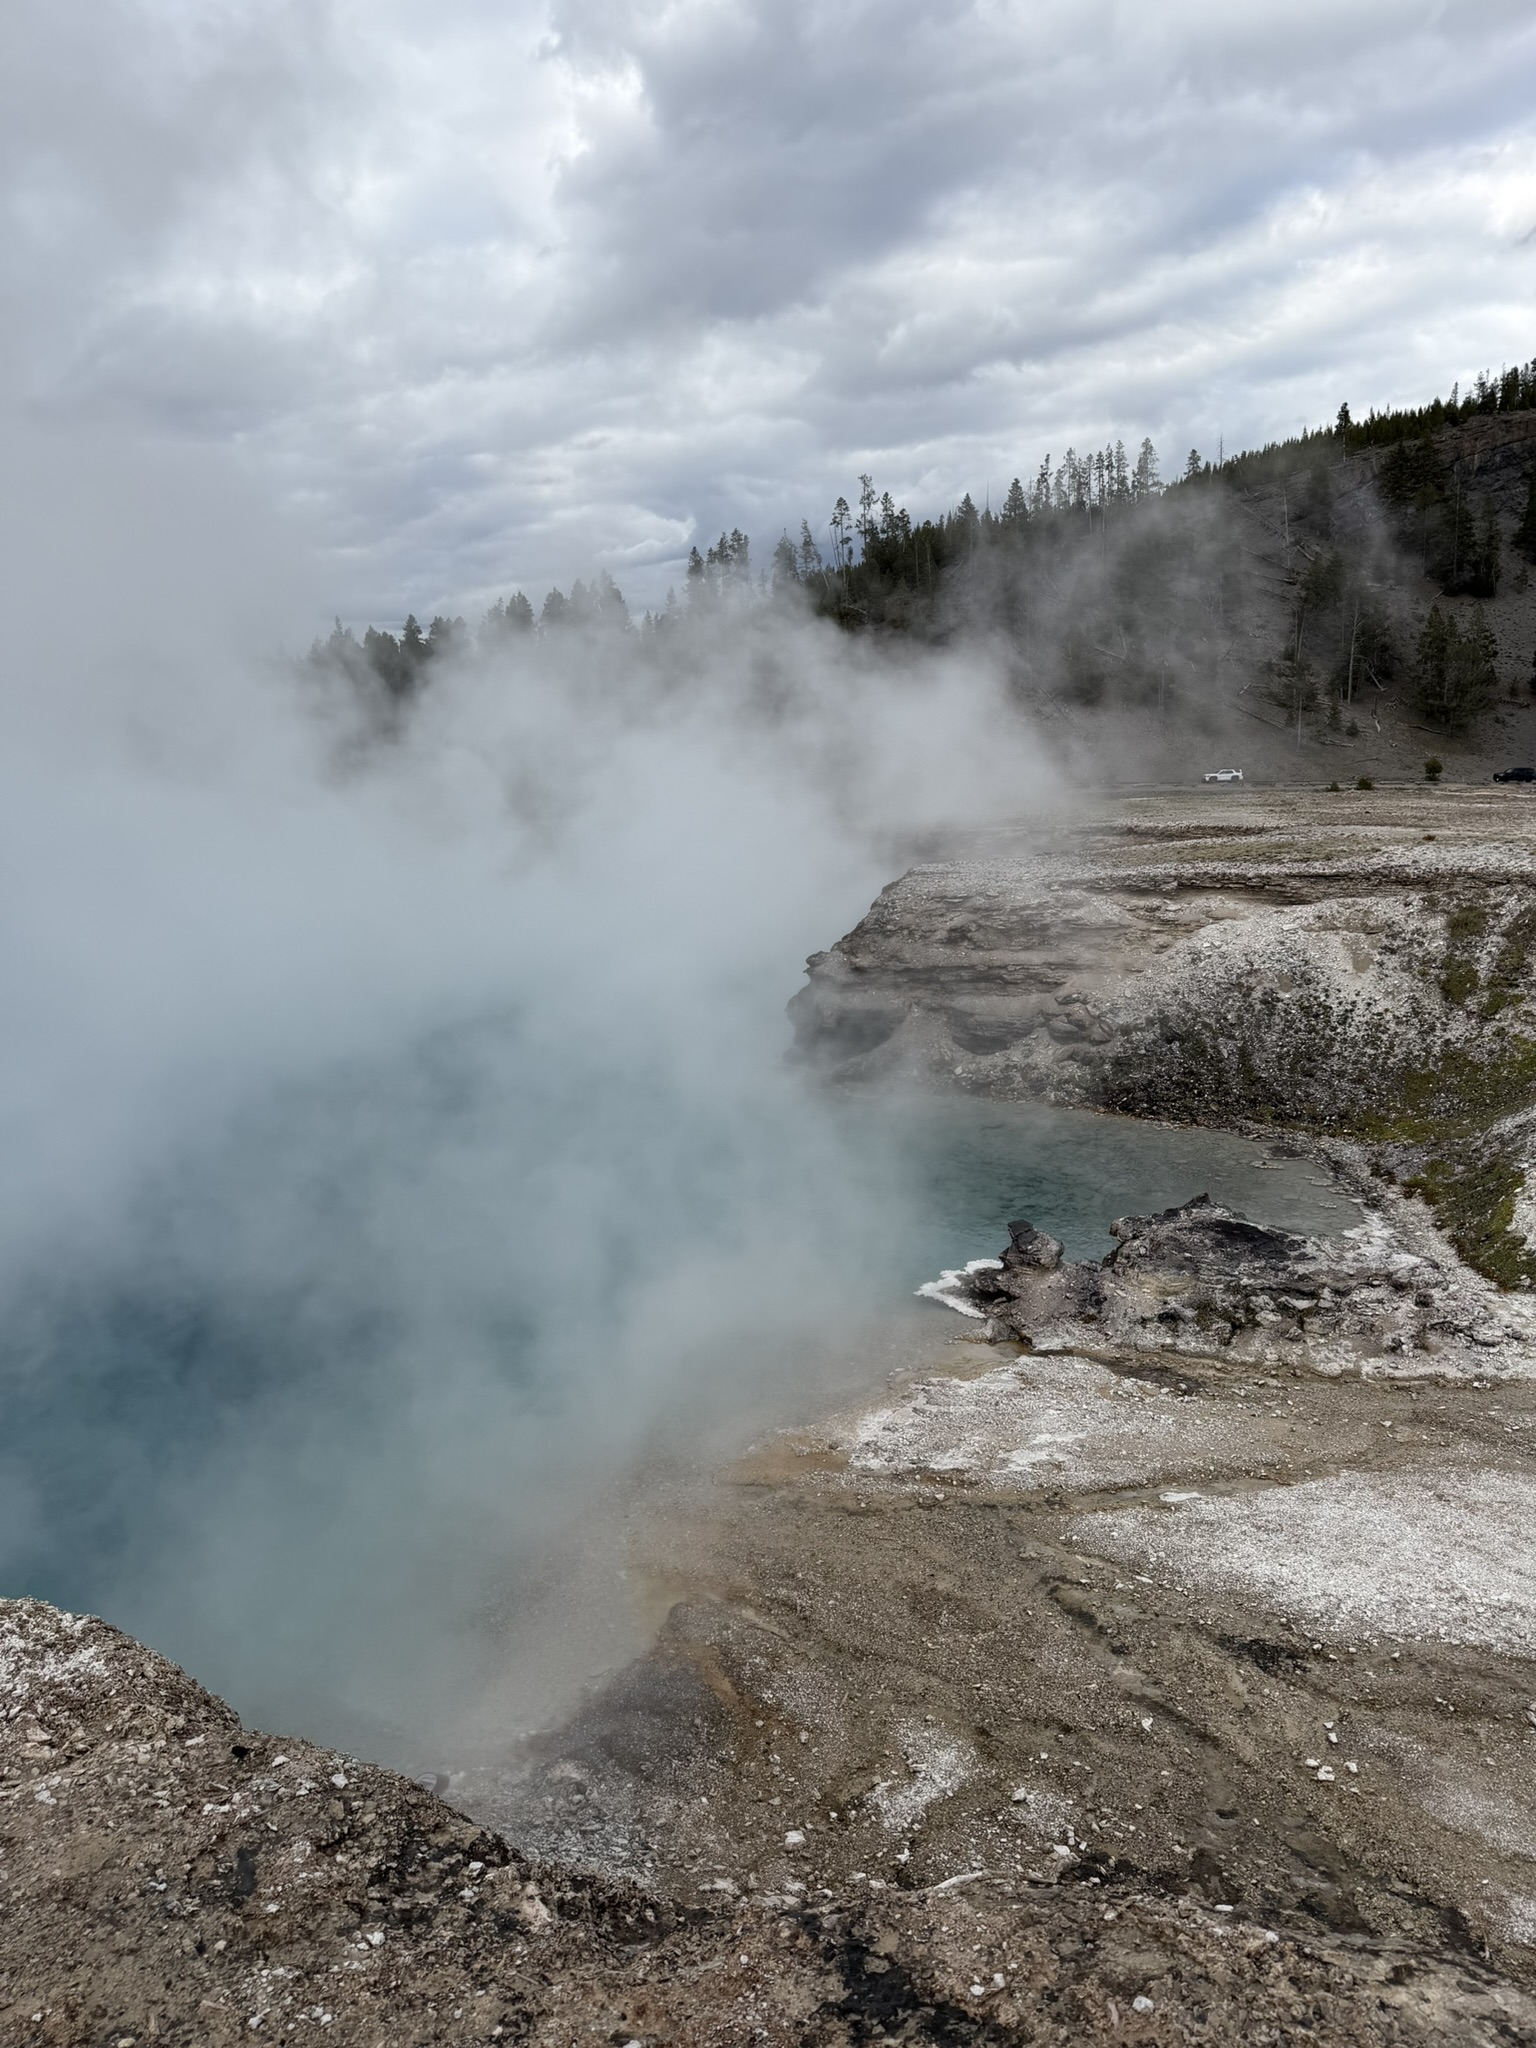
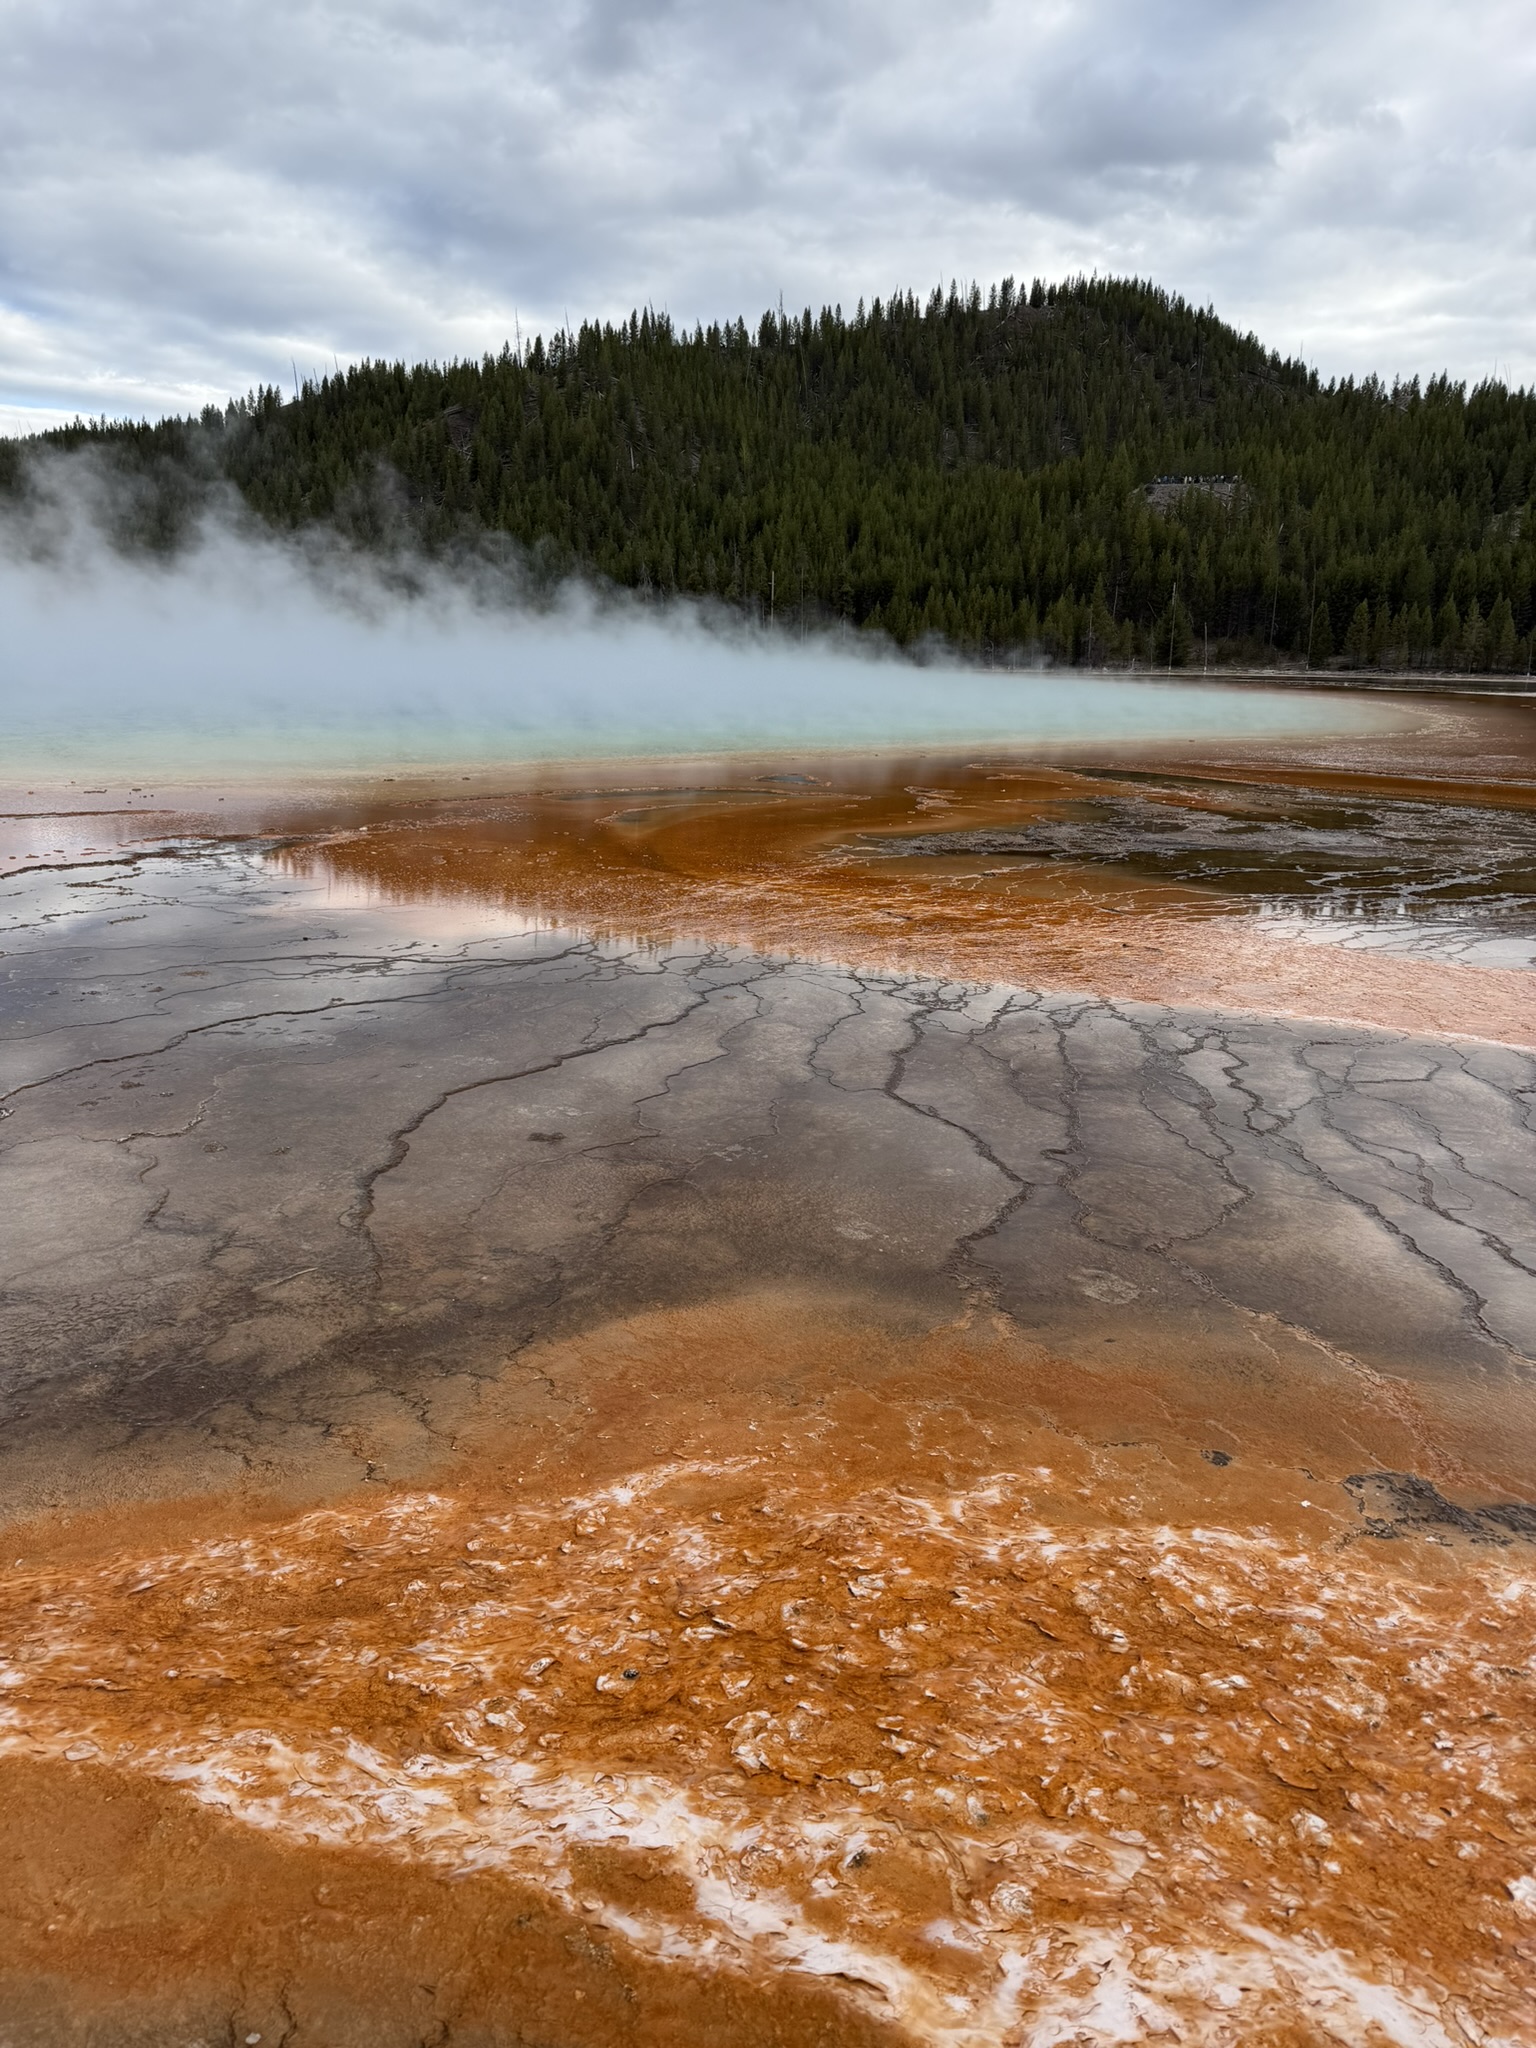
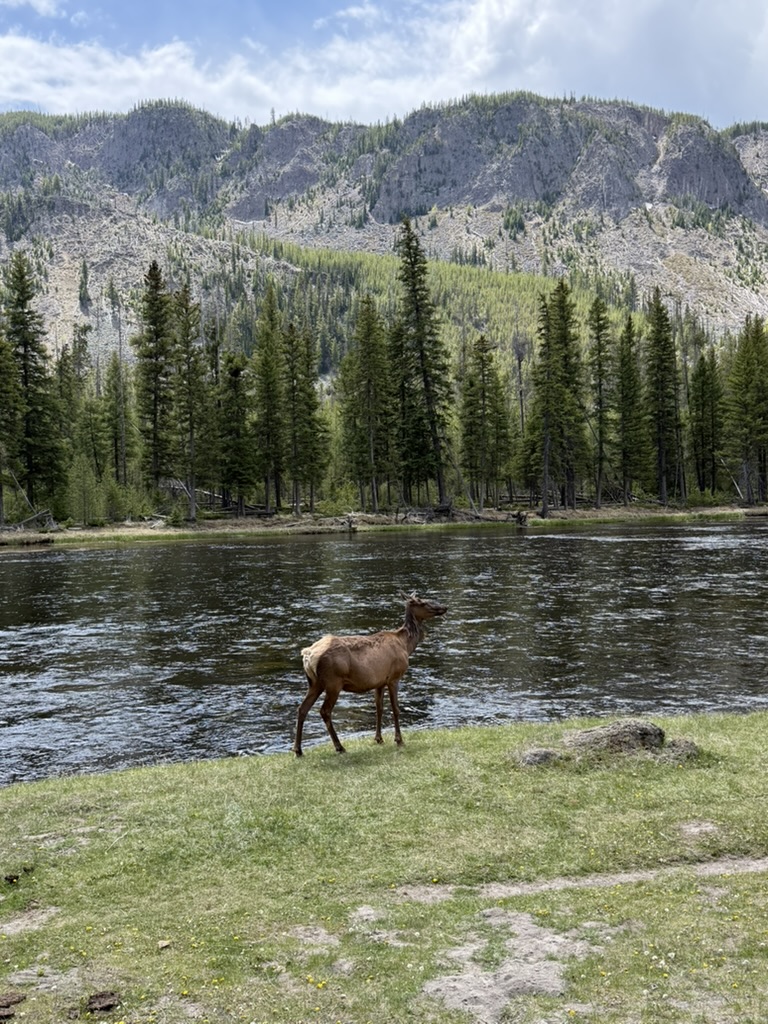
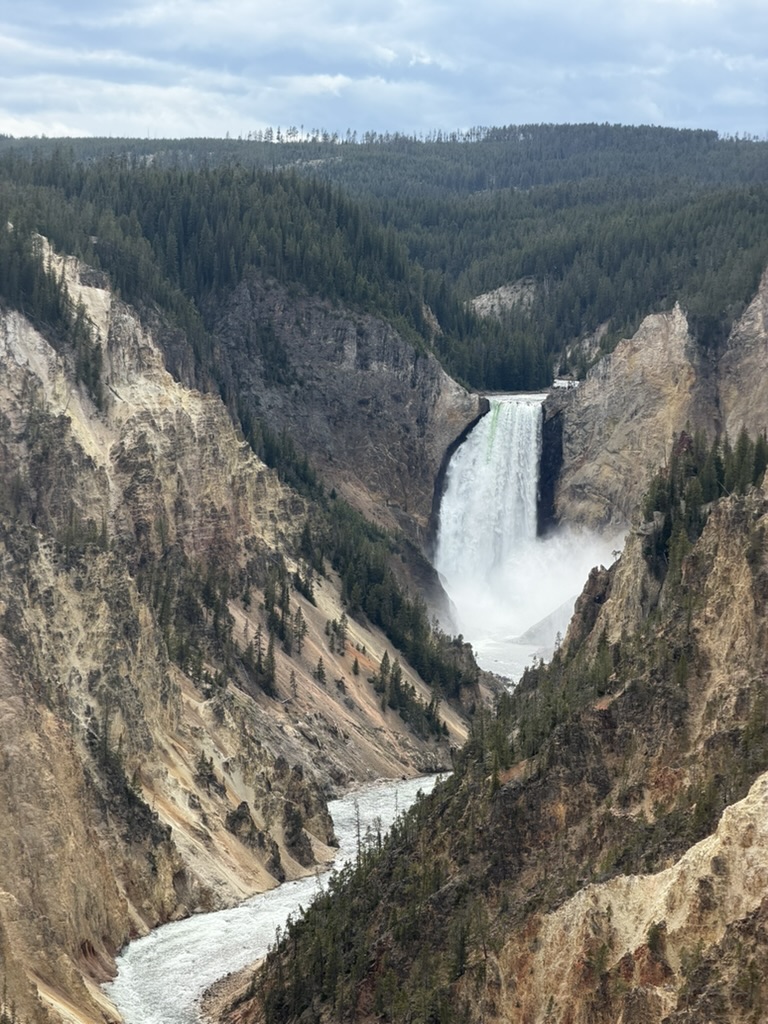
Through My Lens

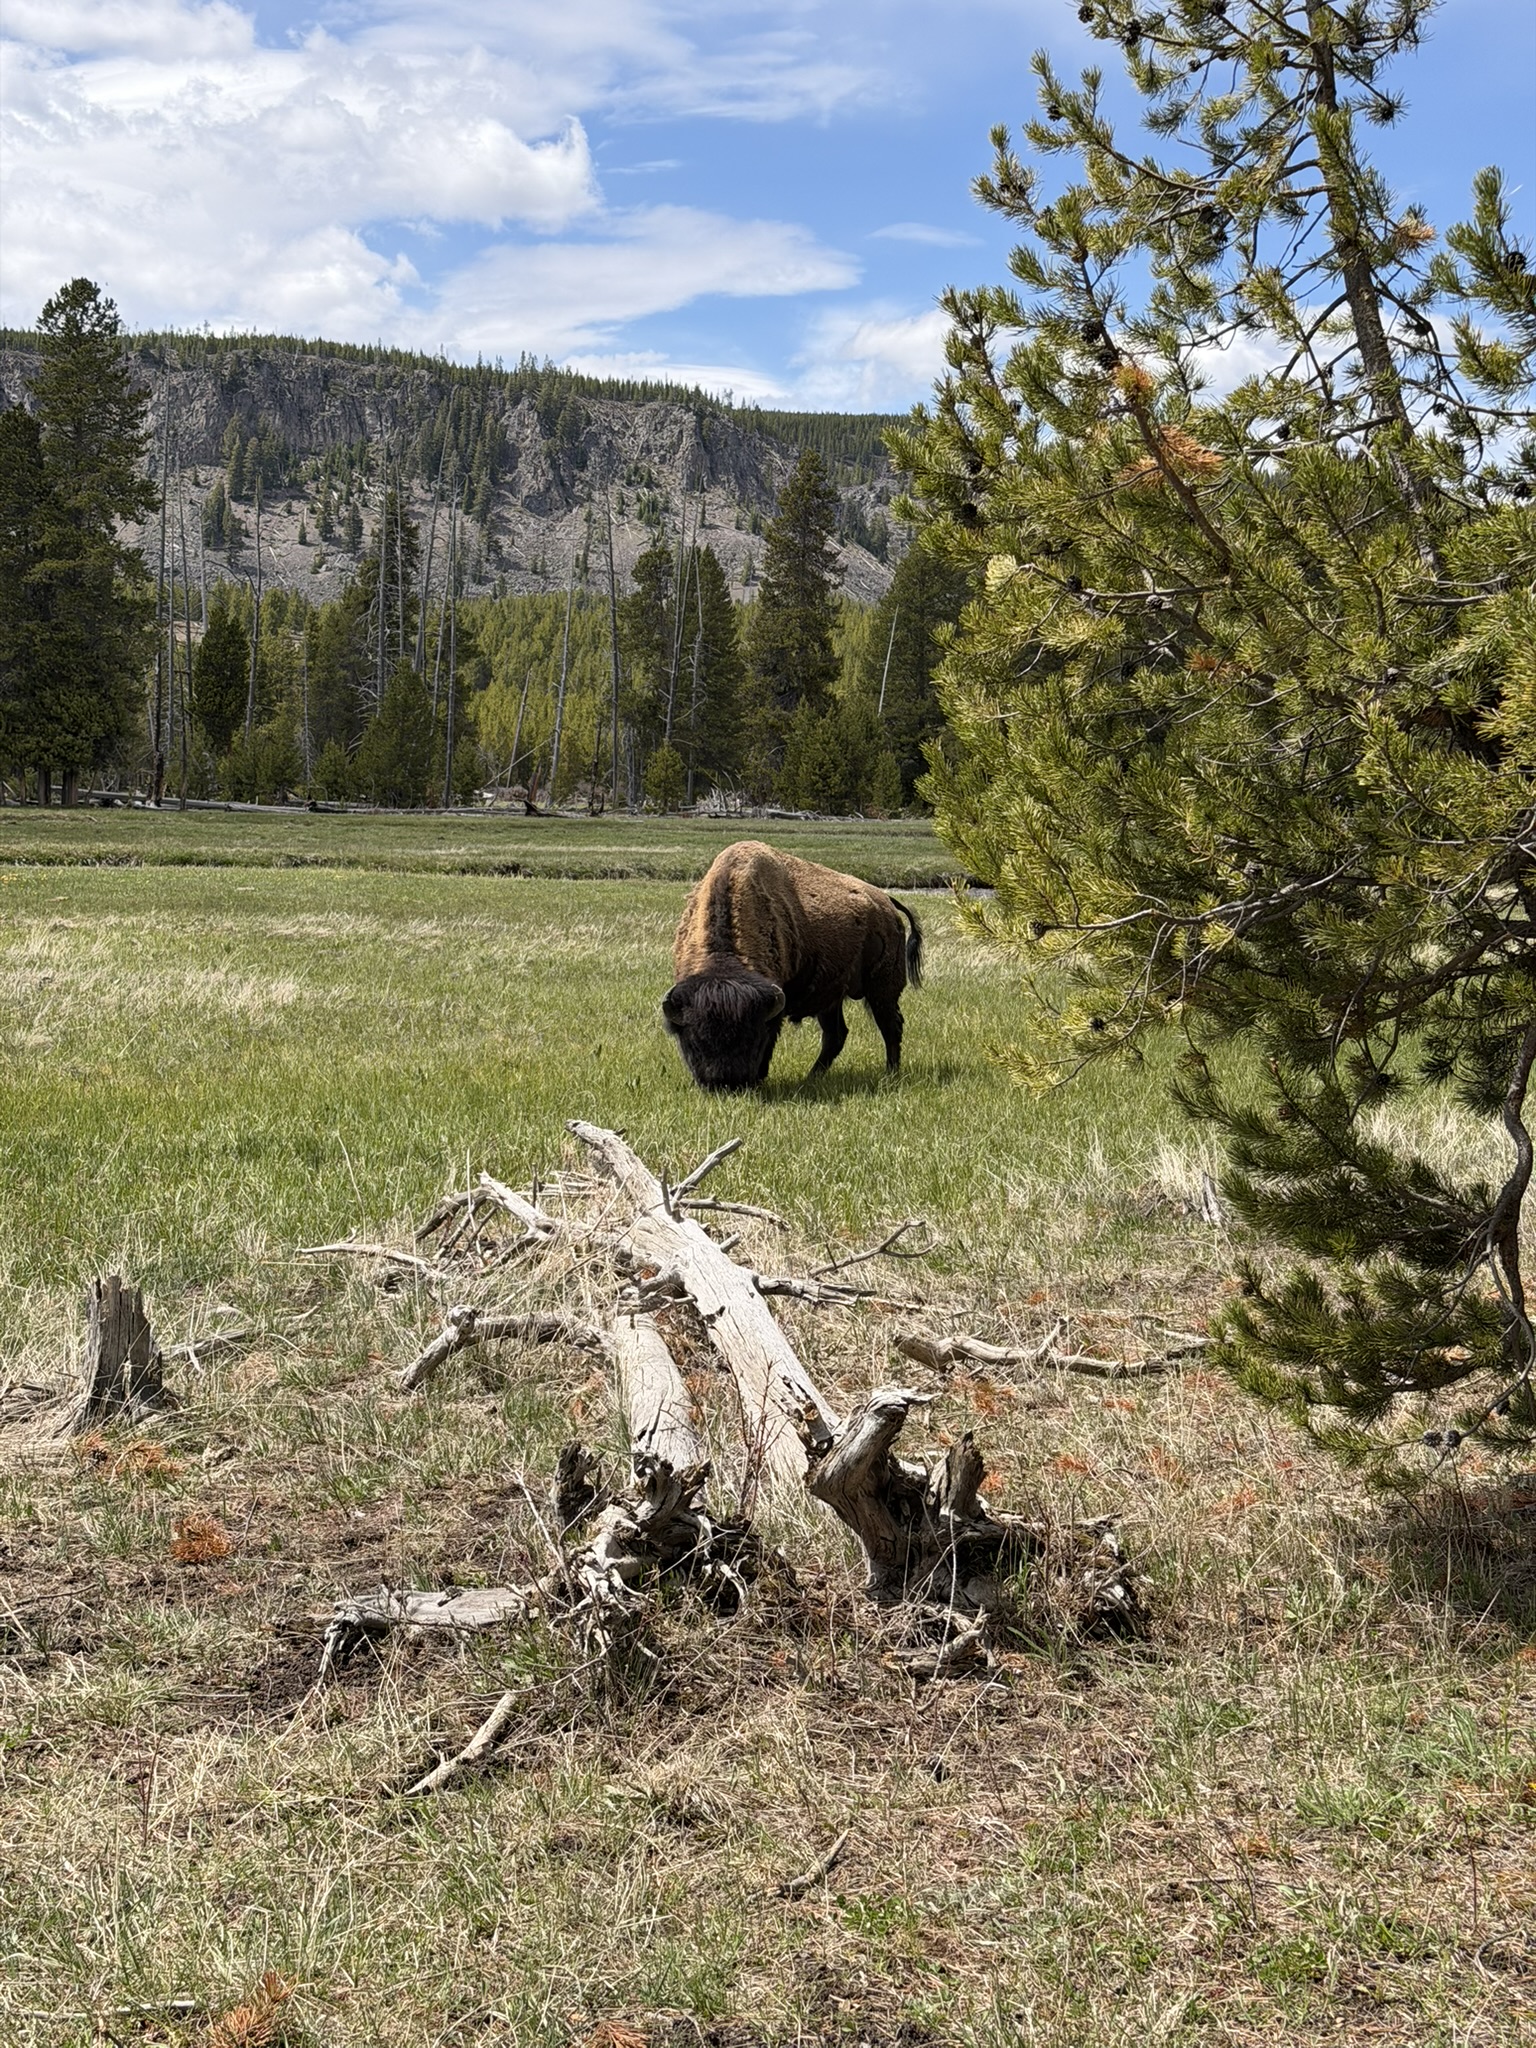
Travel photography across Yellowstone, Grand Teton, New York City, and beyond.

Follow my travel journey on Instagram

@vivek_hanagoji
0 Years Experience
0 Projects Built
0 NFL Teams Served
0 % Data Completeness

More projects on GitHub

I love solving business problems & uncovering hidden data stories

View GitHub
Let's Talk

Contact Me

Open to interesting data engineering roles and collaborations.
Location

Boston, MA

LinkedIn

vivekhanagoji

Resume

Download PDF

Have a question? Get in Touch